Synthesis Evaluation274 names
9 voice models
Can your model
say it correctly?
DOSE v1 tests how accurately nine text-to-speech models pronounce 274 drug names in clinical sentences.
How we build, test, and understand
AI for life sciences.
From the question
to the evidence.
Benchmarks and publications
from the Synthio Labs team.
16 publications
DOSE v1 tests how accurately nine text-to-speech models pronounce 274 drug names in clinical sentences.
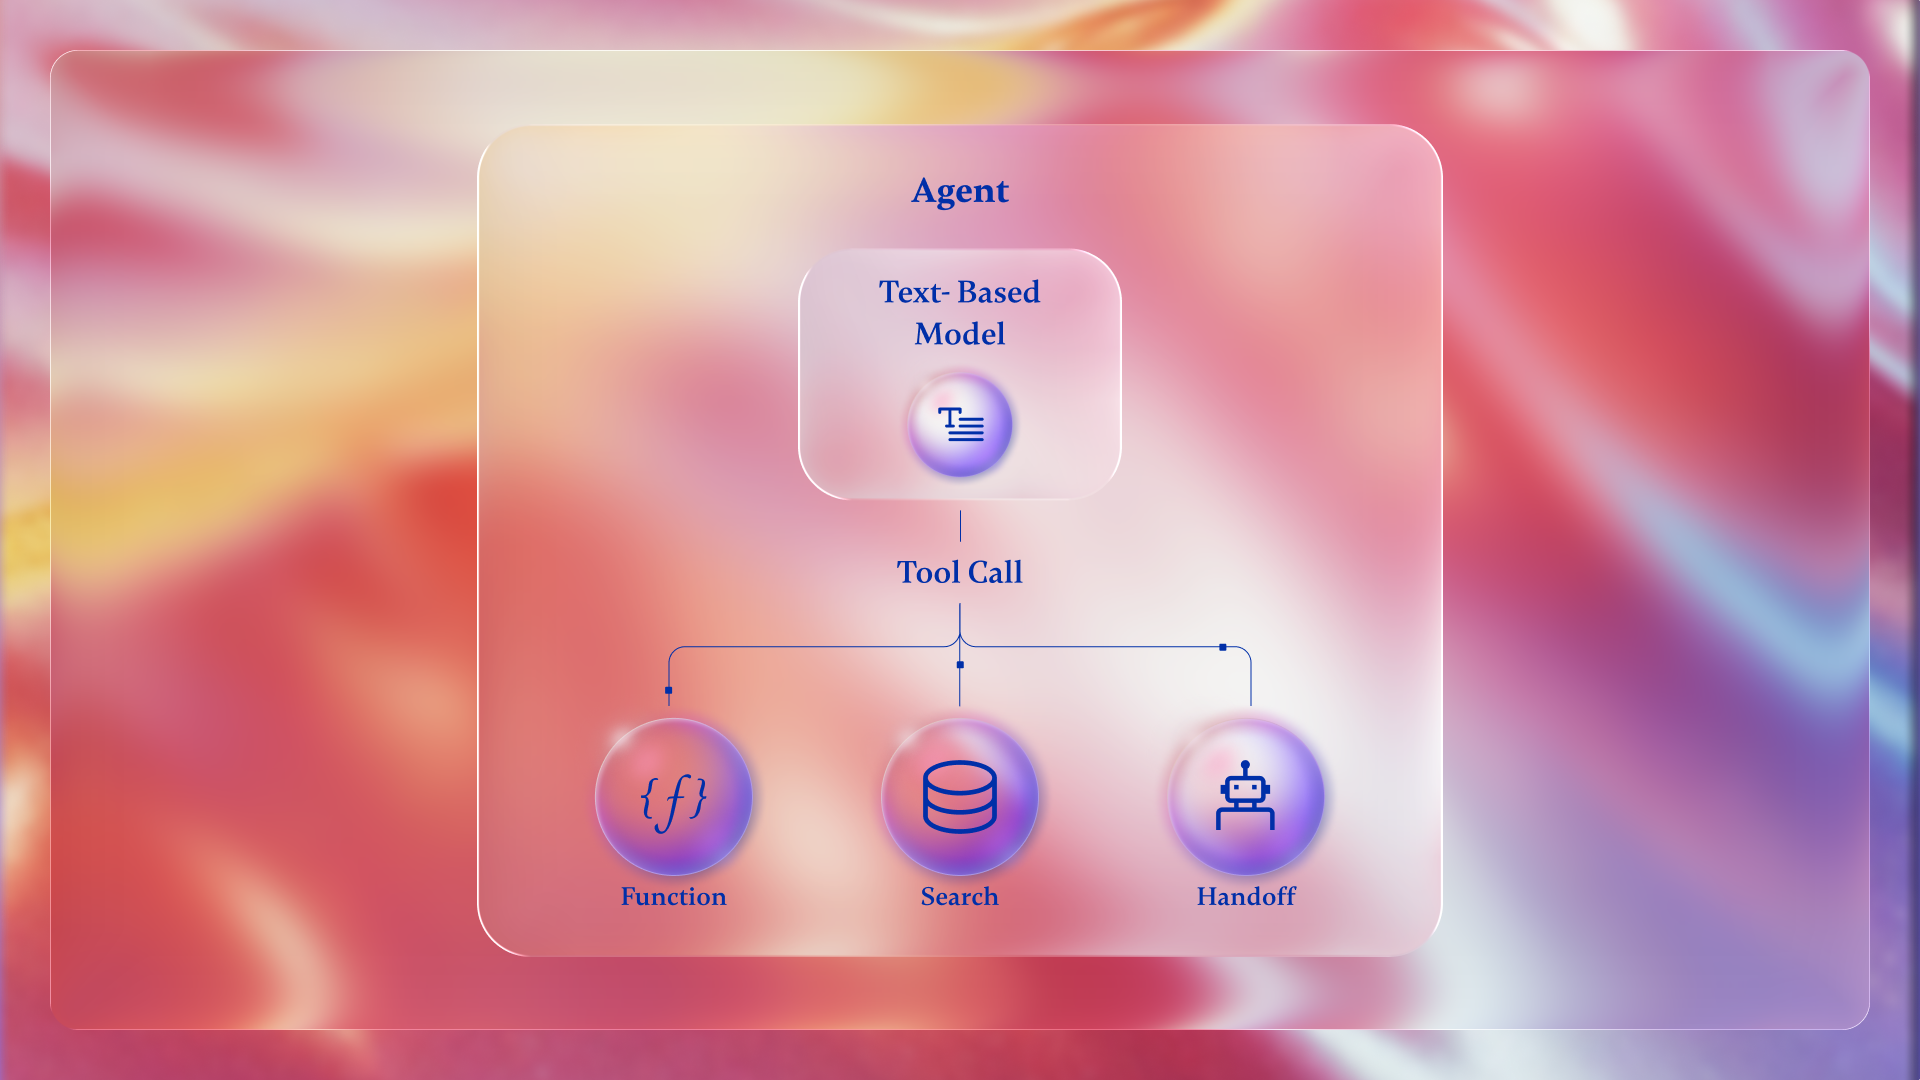
Our agent harness philosophy, and why we measure progress by how much code we get to delete.
Ather agents are not linear systems. They are dynamic, self-modifying graphs. Every conversation is a traversal. Every capability is a node. Every improvement cycle rewrites the graph itself. This document explains the architecture at a conceptual level.
Ather is our AI customer engagement platform for pharma, supporting HCPs across voice, chat, and web. Building it reliably meant solving problems that don't come up in general-purpose agent development.

The right way to evaluate a voice agent is to have another voice agent talk to it.

The goal of agent design is not to pre-specify every move. It is to preserve good judgment across messy variations of the same problem.
Rich, nuanced conversations with HCPs get compressed into simple rows in a database and lose detail.

A critical engineering challenge while building Jarvis was converting unstructured data into precise, structured enterprise actions. We developed the Agentic Extraction Engine to solve this.

From speech, to intelligent agents, back to speech, we explain how we've architected enterprise-grade voice agents for Life Sciences.

When shared context exists across accounts and journeys, the learning compounds. This marks a shift from systems that merely record activity to those that inform action.

Exams test knowledge on paper, not performance in practice. Healthcare demands reproducibility, safety, and responsibility.

We devised a 3 pillar approach called the EMCI framework for ensuring safety and accuracy of our medical voice agents.

A nurse panel study examining the clinical accuracy, empathy, and compliance of our voice AI.

RAG is becoming foundational. In Pharma’s data-rich, compliance-driven world, smart retrieval paired with large context models is the only path to scalable, audit-ready AI.

How we approach input safety, output verification, and guardrails for AI in life sciences.

Built for life sciences, our agents are measured for factual accuracy, regulatory compliance, and professional tone.
Try a different search or explore all publications.
For research collaborations or model submissions, get in touch.